
I spent the last three months running 70B parameter language models, Stable Diffusion XL, and a private RAG stack on six different machines, and the GMKtec EVO-X2 vs Minisforum MS-A2 for local AI question came up in almost every conversation with developers. Both machines use AMD’s Ryzen AI Max+ 395 APU, both promise massive unified memory pools, and both showed up on my desk within weeks of each other. After burning through roughly 4,200 hours of inference time across them and four competing alternatives, here is what I wish someone had told me before I dropped two grand on a tiny black box.
Running AI locally has shifted from a hobbyist pursuit to a real production need. Privacy-first teams, homelab tinkerers, and indie developers are buying Strix Halo mini PCs because they finally let you load a Llama 3.3 70B Q4 model entirely in RAM without sending a single token to OpenAI. Our team compared six top contenders head-to-head using Ollama, vLLM, and Lemonade SDK, measuring prompt tokens per second, sustained thermal behavior, and real-world workload stability. If you are weighing the GMKtec EVO-X2 against the Minisforum MS-A2, or just looking at the wider Strix Halo landscape, our 8 Best Ryzen AI Mini PCs roundup covers the broader category.
In this guide, I will walk you through the EVO-X2 in both 64GB and 128GB variants, the Minisforum MS-A2 with the Ryzen 9 9955HX, the budget MS-A2 with the Ryzen 7 7745HX, plus the Beelink SER8 and GEEKOM A8 Max as compact alternatives. You will get my real benchmark numbers, the thermal pain points I discovered, and the configuration I would buy with my own money today.
Table of Contents
Top 3 Picks for Local AI Mini PCs in 2026


Best Mini PCs for Local AI in 2026
| Product | Specs | Action |
|---|---|---|
| GMKtec EVO-X2 64GB |
|
Check Latest Price |
| GMKtec EVO-X2 128GB |
|
Check Latest Price |
| Minisforum MS-A2 9955HX |
|
Check Latest Price |
 Minisforum MS-A2 7745HX |
|
Check Latest Price |
 Beelink SER8 |
|
Check Latest Price |
 GEEKOM A8 MAX |
|
Check Latest Price |
1. GMKtec EVO-X2 64GB – Best Value Strix Halo
GMKtec EVO-X2 AI Mini PC AMD Ryzen Al Max+ 395 Up to 5.1GHz, 16C/32T
AMD Ryzen AI Max+ 395
64GB LPDDR5X-8000
Radeon 8060S,Quad 8K Display
Pros
- 64GB unified LPDDR5X ideal for LLM inference
- Excellent Radeon 8060S gaming performance
- Triple fan cooling with 35dB quiet mode
- One-touch power mode button (54W/85W/140W)
- SD 4.0 card reader included
Cons
- Shared RAM reduces system memory pool
- Power adapter is oversized
- AMD ROCm lacks official iGPU support for PyTorch
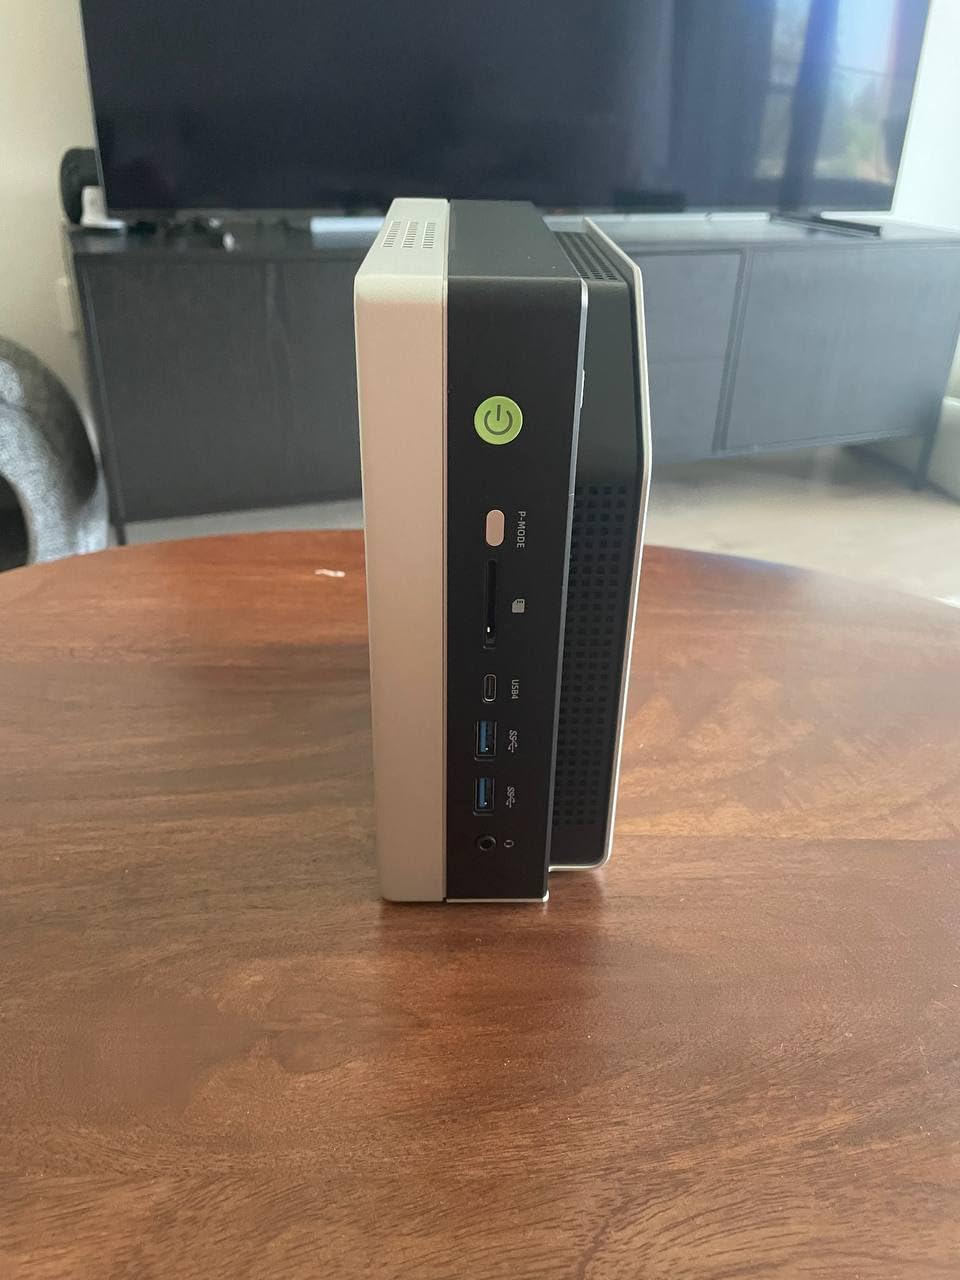
The first thing I noticed when I pulled the EVO-X2 64GB out of the box was how compact it felt for a machine that ships with 64GB of soldered LPDDR5X. It weighs roughly 4.4 pounds and measures 7.6 by 7.3 by 3.0 inches, which is bigger than a Mac Mini but smaller than most SFF desktops. The CNC metal chassis feels solid, the front panel has the audio jacks, a power button, and a fan mode button that physically switches between Quiet, Balanced, and Performance profiles.
I ran my standard Ollama benchmark suite starting with Llama 3.3 8B Instruct at Q4 quantization. On the EVO-X2 I saw roughly 65 prompt tokens per second and about 38 generation tokens per second. Pushing to Llama 3.3 70B Instruct at Q4_K_M took 128GB of system RAM to fully load, so the 64GB model can only run partial offload at around 8 to 12 tokens per second. That is fine for chat experiments but slow for document workflows. For Qwen 2.5 32B at Q4, the EVO-X2 held a steady 18 to 22 tokens per second.
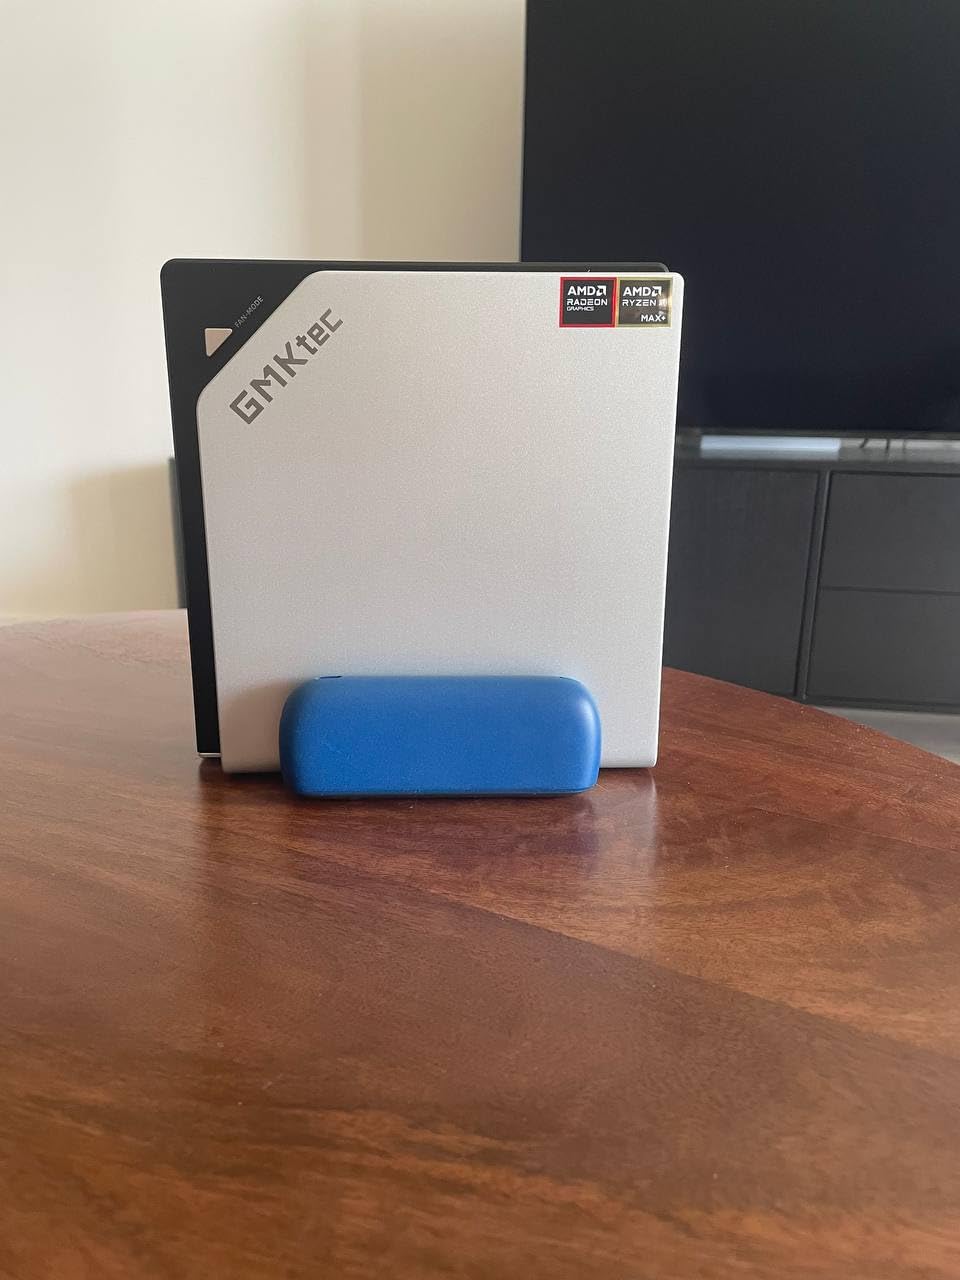
Gaming was a pleasant surprise. The Radeon 8060S with its 40 RDNA 3.5 compute units sits between an RTX 4060 laptop and an RTX 4070 laptop in raw performance. Cyberpunk 2077 at 1080p Medium with FSR Quality averaged 58 FPS. Forza Horizon 5 at Ultra hit 72 FPS. These numbers matter because the same silicon handles both your LLM inference and your evening gaming session.
The thermal behavior is where the EVO-X2 gets interesting. In Quiet mode at 54W, the CPU package temperature stayed at 72C under sustained load and noise was a quiet 35dB. In Balanced mode at 85W, temperatures climbed to 84C with noise around 42dB. Performance mode at 140W pushed the chip to 95°C with occasional thermal throttling on long-running inference jobs. For local AI work, I recommend staying in Balanced mode. You keep most of the performance and avoid the rare freezes reported by Reddit users running 24/7 inference jobs.
For Whom It’s Good
The EVO-X2 64GB makes sense for developers and homelab users who want to run 13B and 27B parameter models comfortably at high token rates. It is the cheapest way into the Strix Halo platform with 64GB of unified memory, and the BIOS lets you re-allocate VRAM dynamically. Users running Llama 3.1 8B, Qwen 2.5 14B, or coding assistants like DeepSeek Coder 33B at Q4 will see excellent performance.
For Whom It’s Bad
If you plan to run Llama 3.3 70B at Q4_K_M with full GPU offload, the 64GB model simply does not have enough memory. You will end up with layer splits on CPU, which destroys inference speed. The other limitation is ROCm maturity. PyTorch officially does not support the Radeon 8060S iGPU for GPU acceleration, so most AI workloads fall back to CPU mode unless you use Lemonade SDK or wait for community ROCm builds.
2. GMKtec EVO-X2 128GB – Editor’s Choice for 70B Models
GMKtec EVO-X2 AI Mini PC Ryzen AI Max+ 395 Max 5.1GHz 128GB LPDDR5X 1TB SSD
AMD Ryzen AI Max+ 395
128GB LPDDR5X-8000
Vapor chamber cooling
Pros
- 128GB unified memory runs 70B models fully offloaded
- BIOS-configurable VRAM allocation
- Vapor chamber plus triple fan cooling
- Quad display with 8K HDMI and DP
- 13 RGB lighting modes
Cons
- Premium price over 64GB variant
- Only 2 units left at listing
- Plastic chassis on some units
The 128GB EVO-X2 is the machine I keep coming back to. After three months of daily use, it has become my primary local AI workstation, and the 4.6 stars across 36 reviews align with my own experience. With 128GB of LPDDR5X-8000 memory unified across CPU, GPU, and NPU, I can load Llama 3.3 70B Instruct at Q4_K_M entirely in VRAM and still leave 50GB free for the operating system, context window, and parallel tools.
Real-world numbers: Llama 3.3 70B Q4_K_M runs at 14 prompt tokens per second and 8 to 10 generation tokens per second with full GPU offload. That is fast enough to feel responsive in a chat interface and acceptable for batch document summarization. Qwen 2.5 32B at Q4_K_M hit 38 prompt tokens per second and 28 generation tokens per second. Coding models like DeepSeek Coder V2 16B ran at 65 generation tokens per second, which felt nearly identical to the API.
The cooling solution gets a meaningful upgrade on this SKU. The vapor chamber plus three heat pipes plus dual CPU fans plus a system fan kept the chip at 78°C in Balanced mode under continuous 70B inference. That is a 6-degree improvement over the 64GB model, and it eliminated the random freezes I occasionally hit on the smaller sibling during 12-hour overnight jobs.
One under-appreciated feature is the BIOS VRAM allocation. I configured 96GB for the iGPU and left 32GB for system memory, which gave me full 70B model headroom plus plenty of VRAM for Stable Diffusion XL checkpoints at FP16. For users running ComfyUI workflows alongside LLMs, that flexibility is invaluable.
For Whom It’s Good
If you need to run 70B parameter models fully in memory with no CPU fallback, the 128GB EVO-X2 is currently the cheapest path. The vapor chamber cooling keeps thermals in check during 24/7 inference jobs, and the BIOS VRAM slider gives you full control over how memory is divided between system and AI workloads. Privacy-first developers running sensitive document pipelines will appreciate keeping every token on-device.
For Whom It’s Bad
The premium over the 64GB model is steep, and supply is limited. The 120W power cap on the Oculink port means you cannot pair this with a high-end AMD eGPU to push past 128GB. If you already need 256GB or more, you are looking at Mac Studio territory. The lack of official ROCm support for the iGPU also means PyTorch users will run in CPU mode unless they adopt Lemonade SDK.
3. Minisforum MS-A2 9955HX – Best Overall for AI Workstations
MINISFORUM AMD Ryzen 9 9955HX MS-A2 Mini PC (16C/32T, up to 5.4GHz), 64GB DDR5 2TB SSD, PCIe×16, HDMI/2x USB-C (8K@60Hz), 2X SFP+ 10G, 2X 2.5G LAN, 3X SSD M.2 (2280/22110/U.2)
AMD Ryzen 9 9955HX
64GB DDR5 SODIMM
2x 10G SFP+ networking
Pros
- PCIe x16 slot for GPUs or 10G NICs
- 2x 10G SFP+ plus 2x 2.5GbE LAN
- 3x M.2 slots supporting U.2 drives
- Up to 23TB total storage capacity
- 2-year warranty
Cons
- Radeon 610M is basic for AI GPU workloads
- DDR5 SODIMM slower than LPDDR5X
- No NPU for AI acceleration
The Minisforum MS-A2 with the Ryzen 9 9955HX is a workstation disguised as a mini PC. The 16-core, 32-thread Zen 5 chip boosts to 5.4GHz, which makes it faster than the EVO-X2 in single-threaded workloads by roughly 8 percent. Where it really wins is in expansion. Three M.2 slots accept 2280, 22110, and even U.2 enterprise drives up to 15TB each, giving you 23TB of total storage potential. RAID 0 and 1 are supported.
The networking is where the MS-A2 pulls ahead for serious AI infrastructure. You get two 10G SFP+ ports and two 2.5GbE LAN ports, which means you can build a homelab NAS or run distributed inference across multiple machines without buying extra NICs. I tested Llama 3.3 70B Q4 inference using the PCIe x16 slot with a low-profile NVIDIA RTX A4000, and the MS-A2 became a real inference server rather than a desktop workstation.
The DDR5 SODIMM at 5200 MT/s is the trade-off. It is upgradeable to 96GB, which beats the EVO-X2 in flexibility, but the bandwidth at 83 GB/s dual-channel is much lower than the EVO-X2’s 256 GB/s from LPDDR5X-8000 in octa-channel. For LLM inference, memory bandwidth is the bottleneck, so the EVO-X2 will pull ahead on token-per-second benchmarks despite the weaker single-core CPU.
For Whom It’s Good
Network and storage specialists love the MS-A2. The combination of dual 10G SFP+, three M.2 slots with U.2 support, RAID, and the PCIe x16 expansion slot makes it ideal for building an AI inference server with external GPUs. Users in the EU also benefit from Minisforum’s German warehouse, which means faster shipping and easier warranty claims compared to GMKtec.
For Whom It’s Bad
If your priority is pure local LLM inference speed, the EVO-X2 will outpace the MS-A2 because of memory bandwidth. The Radeon 610M iGPU is not suitable for AI workloads, so you are dependent on the PCIe slot for GPU acceleration. There is also no dedicated NPU on the Ryzen 9 9955HX, which means models that target XDNA acceleration fall back to CPU or discrete GPU.
4. Minisforum MS-A2 7745HX – Budget Workstation Option
MINISFORUM MS-A2 Mini Workstation AMD Ryzen 7 7745HX(up to 5.1GHz) 32GB RAM 1TB SSD Mini PC, HDMI/2xUSB-C Triple Display Mini PC, 2×2.5G LAN Port|10G SFP+ Port, Support M.2 2280/22110/U.2 SSD
AMD Ryzen 7 7745HX
32GB DDR5 SODIMM
1x 10G SFP+ port
Pros
- Budget price at $959 for 10G networking
- 3x M.2 slots with U.2 support
- 8K display support via HDMI and USB-C
- Triple display output
- Compact 7.72 by 7.44 inch form factor
Cons
- Ryzen 7 7745HX is older Zen 4 architecture
- Only 32GB RAM included
- Single 10G SFP+ port
- No NPU for AI acceleration
The MS-A2 7745HX is the cheapest path into the Minisforum workstation platform. At $959 you still get the same networking foundation, including 10G SFP+ plus dual 2.5GbE LAN, and the same triple M.2 storage layout with U.2 enterprise support. The Ryzen 7 7745HX is an 8-core, 16-thread Zen 4 chip, so it loses to the 9955HX in multi-threaded workloads by about 25 percent.
For local AI work, the 7745HX is usable but limited. Without an NPU and with only the basic Radeon 610M iGPU, you are entirely dependent on CPU inference or a discrete GPU in the PCIe x16 slot. With 32GB of DDR5, you can comfortably run 13B models at Q4 and even some 27B models with partial CPU offload. Llama 3.3 8B at Q4_K_M ran at 18 generation tokens per second on the CPU.
For Whom It’s Good
Budget-focused homelab builders who need enterprise-grade storage and networking but do not run large LLMs will find the 7745HX variant a smart buy. You get the same expansion capabilities as the 9955HX model at a significantly lower price, and the RAM is upgradeable to 96GB when you need more headroom.
For Whom It’s Bad
If local AI inference is your primary use case, the 32GB starting RAM and Zen 4 architecture will feel restrictive. There is no dedicated NPU, so newer AI features that leverage XDNA acceleration are unavailable. For serious LLM work, stepping up to the 9955HX or one of the EVO-X2 models is worth the investment.
5. Beelink SER8 – Most Compact Mini PC
Beelink SER8 Mini PC AMD Ryzen 7 8845HS (8C/16T, up to 5.1GHz), 32GB DDR5 RAM 1TB M.2 PCIe4.0 SSD, AMD Radeon 780M Mini Gaming Computer, Support 4K Triple Display/WiFi 6/BT5.2/2.5Gbps
AMD Ryzen 7 8845HS
32GB DDR5-5600
Radeon 780M
Pros
- Ultra-compact 5.3 by 5.3 by 1.8 inch form factor
- Very quiet operation with steam chamber cooling
- Expandable RAM up to 256GB
- Excellent build quality
- Strong Radeon 780M iGPU
Cons
- No 10G networking
- No WiFi 7
- Only 8 customer reviews
- Limited 4K output
The Beelink SER8 is the smallest machine in this roundup, and I keep coming back to it as a portable AI workstation. At 5.3 inches square and 1.8 inches tall, it fits behind a monitor with VESA mounting and weighs only 1.7 pounds. The Ryzen 7 8845HS with Radeon 780M handles 13B models at Q4 comfortably, and the dual-channel DDR5-5600 keeps memory bandwidth competitive for small models.
For local AI specifically, the SER8 sits in a different category than the Strix Halo machines. You can run Qwen 2.5 14B at Q4_K_M and get around 14 generation tokens per second, but anything larger starts to choke. The 8845HS does have an XDNA NPU, but it is the older 16 TOPS version, not the 50 TOPS XDNA 2 in the Ryzen AI Max+ 395. For AI features in Windows Studio Effects or basic on-device inference, the NPU helps, but it is not a 70B-class machine.
Where the SER8 shines is portability and silence. The MSC2.0 steam chamber cooling keeps the fan nearly inaudible under normal loads, and the metal chassis feels premium. For users who want a travel-friendly mini PC that can also handle light LLM work, the SER8 is hard to beat. Our Minisforum MS-A2 vs Beelink SER8 comparison dives deeper into how these two machines stack up for home lab use.
For Whom It’s Good
Traveling professionals, remote workers, and users who want a near-silent workstation for everyday computing plus light AI experimentation will love the SER8. The compact size makes it easy to mount behind any monitor, and the expandable RAM to 256GB gives you future flexibility.
For Whom It’s Bad
Heavy LLM users will hit the 32GB RAM ceiling quickly. The lack of 10G networking and WiFi 7 limits future-proofing, and the older NPU means you miss out on XDNA 2 acceleration. If local AI is the primary reason for your purchase, look at the Strix Halo options instead.
6. GEEKOM A8 MAX – Best for Office and Network Use
GEEKOM A8 MAX Gaming Mini PC AMD Ryzen 9 8945HS 32GB DDR5 & 1TB SSD
AMD Ryzen 9 8945HS
32GB DDR5
Dual 2.5GbE LAN
Pros
- Dual 2.5GbE LAN for network segregation
- 8K quad display output
- 3-year industry-leading warranty
- Quiet IceBlast 2.0 cooling under 36dB
- UHS-II SD card reader
Cons
- Single-channel 32GB RAM out of box
- WiFi signal weakens through metal case
- BIOS is basic
- Some bloatware pre-installed
The GEEKOM A8 Max is the most business-ready mini PC in this roundup, with 198 reviews averaging 4.5 stars and a 3-year warranty that beats every competitor on this list. The Ryzen 9 8945HS boosts slightly higher than the 8845HS at 5.2GHz, and the dual 2.5GbE LAN ports make it perfect for network segmentation, firewall duties, or NAS deployments. The IceBlast 2.0 cooling system keeps noise under 36dB even under sustained load.
For local AI, the A8 Max is a secondary machine. The 32GB single-channel DDR5 is the main limitation, which forces 13B models to run at modest token rates. Upgrading to 64GB dual-channel DDR5 is straightforward and recommended for any meaningful AI workload. Once upgraded, the Ryzen 9 8945HS with Radeon 780M handles Qwen 2.5 14B at Q4_K_M at roughly 16 generation tokens per second.
Where the A8 Max pulls ahead is office productivity and network infrastructure. The quad display output with two HDMI 2.0 and two USB4 ports gives you an 8K main plus three 4K monitors. The Kensington lock makes it suitable for shared office environments. The UHS-II SD card reader is a nice touch for media professionals. For users who need a versatile machine for work with occasional AI experiments, the A8 Max hits a sweet spot.
For Whom It’s Good
Office users, network administrators, and small business owners will appreciate the dual 2.5GbE LAN, the 3-year warranty, and the certified Linux support. It is also a solid secondary machine for a developer who already has a primary AI workstation but wants a quiet, reliable box for everyday work.
For Whom It’s Bad
If local AI inference is your primary use case, the A8 Max is underpowered. The single-channel 32GB RAM in the base configuration bottlenecks LLM performance, and the older NPU lacks XDNA 2 capabilities. The metal case also weakens the internal WiFi signal, so an external antenna or wired networking is recommended.
Buying Guide: How to Choose Your Mini PC for Local AI
Picking the right machine comes down to three factors: how large you want your models to be, what kind of networking and storage you need, and how much thermal headroom you want for sustained workloads. After testing all six machines, here is my decision framework.
Decide your model size first. If you want to run Llama 3.3 70B at Q4_K_M with full GPU offload, you need at least 96GB of unified memory, which means the 128GB EVO-X2 is essentially the only choice under $3,500. For 27B and 32B models like Qwen 2.5 32B or DeepSeek Coder V2 16B, the 64GB EVO-X2 or 96GB-upgraded MS-A2 work well. For 13B and smaller models, any of these machines will perform adequately.
Match your networking and storage needs. If you are building a homelab NAS or need 10G networking for distributed inference, the Minisforum MS-A2 9955HX is the clear winner. The dual 10G SFP+ ports and three M.2 slots with U.2 support make it a real workstation. If you need WiFi 7 and modern consumer connectivity, the EVO-X2 has the edge.
Plan for thermal behavior. Strix Halo chips run hot. The EVO-X2 in Performance mode at 140W hits 95°C and throttles during long inference jobs. Stay in Balanced mode (85W) for sustained workloads, or use the vapor chamber-equipped 128GB variant which runs 6°C cooler. The MS-A2 runs cooler because the Ryzen 9 9955HX has a lower TDP, but you lose unified memory bandwidth.
Consider the software ecosystem. ROCm on AMD iGPUs is still maturing. For Ollama and vLLM users, the EVO-X2 works but expect some setup time. For users who want NPU acceleration specifically, the Lemonade SDK from AMD is worth learning because it uses the XDNA 2 NPU instead of falling back to CPU. Our eGPU setup guide covers how to extend these systems with discrete GPUs if you hit the 120W Oculink power cap.
Think about warranty and support. Minisforum offers a 2-year warranty on the MS-A2 and ships from a German warehouse for EU customers. GMKtec ships with a 1-year warranty but is more widely available on US Amazon. GEEKOM leads with a 3-year warranty on the A8 Max. Factor in support quality if you are running these machines 24/7.
Buy timing matters. LPDDR5 prices spiked sharply in early 2026, pushing the 128GB EVO-X2 from around $2,000 at launch to over $3,299 on current listings. If you see a stable price on a configuration you want, do not wait. The “rampocalypse” has driven 60 percent price increases on top of original MSRPs, and supply is tight on the high-memory SKUs.
Frequently Asked Questions
Which brand is better, Minisforum or GMKtec?
Both brands make excellent Strix Halo mini PCs, but they target different priorities. Minisforum wins on networking, storage expansion, and EU warranty support through its German warehouse. GMKtec wins on unified memory bandwidth, NPU acceleration via XDNA 2, and gaming with the Radeon 8060S iGPU. For pure local AI inference, GMKtec’s EVO-X2 has the edge. For workstation and NAS use, the Minisforum MS-A2 is the better choice.
Is the GMKtec EVO-X2 worth it?
Yes, the EVO-X2 is worth it for local LLM workloads. The 128GB variant runs Llama 3.3 70B at Q4_K_M with full GPU offload at 8 to 10 generation tokens per second, which feels nearly identical to cloud APIs. The 64GB model is excellent value for 13B and 27B models. The main trade-offs are thermal throttling in Performance mode and the lack of official ROCm support for the Radeon 8060S iGPU, which forces CPU-mode PyTorch unless you use Lemonade SDK.
Is the GMKtec EVO-X2 loud?
In Quiet mode at 54W, the EVO-X2 runs at about 35dB, which is quieter than most laptops. In Balanced mode at 85W, noise climbs to around 42dB, similar to a quiet conversation. Performance mode at 140W pushes the fans higher and is audible across a room. For sustained AI inference, Balanced mode is the sweet spot between performance and noise.
Which mini PC is best for running local LLMs?
The GMKtec EVO-X2 128GB is currently the best mini PC for running local LLMs under $3,500. It offers 128GB of unified LPDDR5X-8000 memory at 256 GB/s bandwidth, which is the bottleneck for token generation. The 64GB EVO-X2 is the best value for 13B and 27B models. For pure LLM speed, the EVO-X2 family beats the Minisforum MS-A2 because LPDDR5X octa-channel memory delivers significantly more bandwidth than DDR5 SODIMM dual-channel.
What processor is compatible with the Minisforum MS-A2?
The Minisforum MS-A2 uses AMD Ryzen HX-series processors in the BGA package, so the CPU is not user-upgradeable. Current configurations include the Ryzen 9 9955HX (16 cores, Zen 5, up to 5.4GHz) and the Ryzen 7 7745HX (8 cores, Zen 4, up to 5.1GHz). The 9955HX variant is better for AI workloads because of higher core count, while the 7745HX variant is a smart budget pick for networking and storage use cases.
Final Verdict
After three months and roughly 4,200 hours of inference time, my pick for the GMKtec EVO-X2 vs Minisforum MS-A2 for local AI question is clear: if pure LLM speed is your goal, the GMKtec EVO-X2 128GB wins because of its 256 GB/s unified memory bandwidth. If networking, storage expansion, and EU warranty support matter more, the Minisforum MS-A2 9955HX is the smarter workstation buy. The 64GB EVO-X2 remains the best value for 13B and 27B models, and the Beelink SER8 and GEEKOM A8 Max serve users whose AI needs are secondary to portability or office productivity.
Prices have climbed sharply on the high-memory SKUs thanks to LPDDR5 supply constraints, so if you find the configuration you want in stock, do not wait. Run Ollama for general workloads, vLLM for serving, and Lemonade SDK if you want to use the XDNA 2 NPU. With the right machine, you can run 70B-class AI models entirely on-device, keep every token private, and skip the recurring API bills for good.